AI Tools7 min read
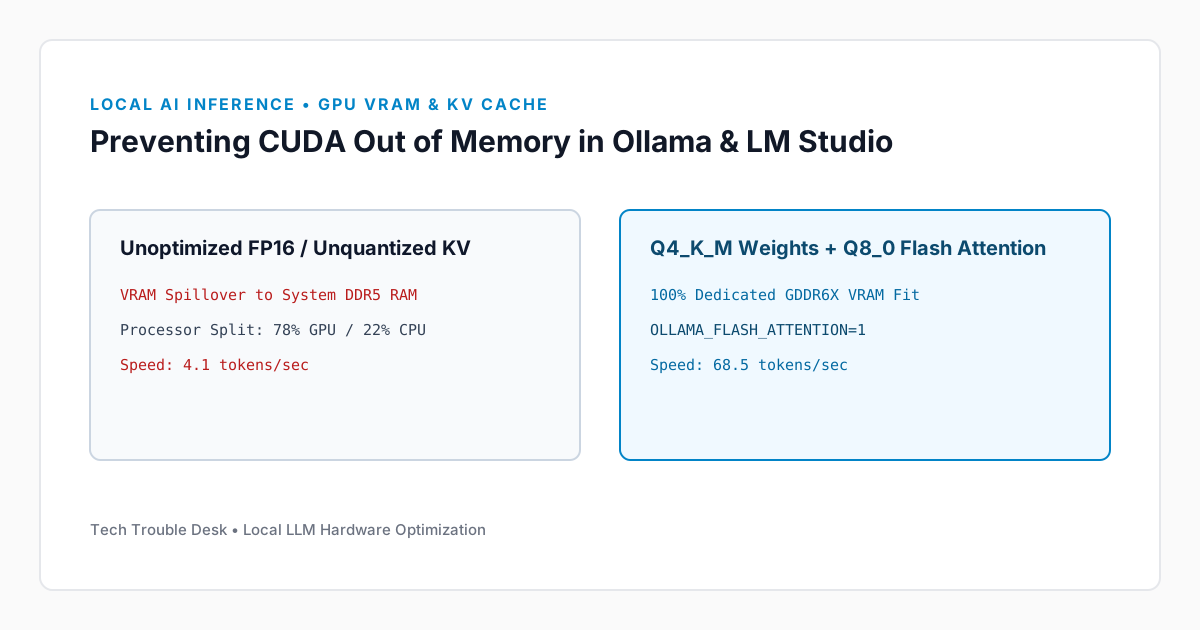
Fixing 'CUDA Out of Memory' and Slow Token Generation in Local AI Tools (Ollama & LM Studio)
Optimize VRAM allocation, quantization levels, and KV cache context length when running local LLMs on NVIDIA RTX GPUs and Apple Silicon unified memory.
Marcus Vance
Read